← Publications / Safety Post-Training & Alignment
AlignTune: Modular Toolkit for Post-Training Alignment of Large Language Models
R E Zera Marveen Lyngkhoi, Chirag Chawla, Pratinav Seth, Utsav Avaiya, Soham Bhattacharjee, Mykola Khandoga, Rui Yuan, Vinay Kumar Sankarapu
Abstract
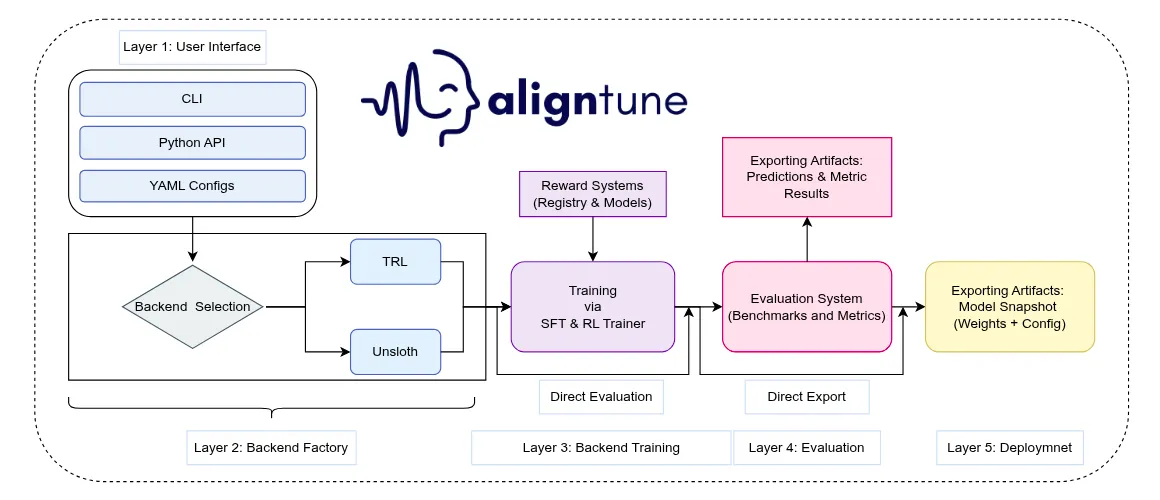
Post-training alignment is central to deploying large language models (LLMs), yet practical workflows remain split across backend-specific tools and ad-hoc glue code, making experiments hard to reproduce. We identify backend interference, reward fragmentation, and irreproducible pipelines as key obstacles in alignment research. We introduce AlignTune, a modular toolkit exposing a unified interface for supervised fine-tuning (SFT) and RLHF-style optimization with interchangeable TRL and Unsloth backends. AlignTune standardizes configuration, provides an extensible reward layer (rule-based and learned), and integrates evaluation over standard benchmarks and custom tasks. By isolating backend-specific logic behind a single factory boundary, AlignTune enables controlled comparisons and reproducible alignment experiments.
Cite
@misc{lyngkhoi2026aligntune,
  title         = {{AlignTune: Modular Toolkit for Post-Training Alignment of Large Language Models}},
  author        = {R E Zera Marveen Lyngkhoi and Chirag Chawla and Pratinav Seth and Utsav Avaiya and Soham Bhattacharjee and Mykola Khandoga and Rui Yuan and Vinay Kumar Sankarapu},
  note          = {Pre-Print},
  year          = {2026},
  eprint        = {2602.09621},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2602.09621}
}